Tuesday, 4 December 2018

Why Being the Loudest Makes You the Weakest
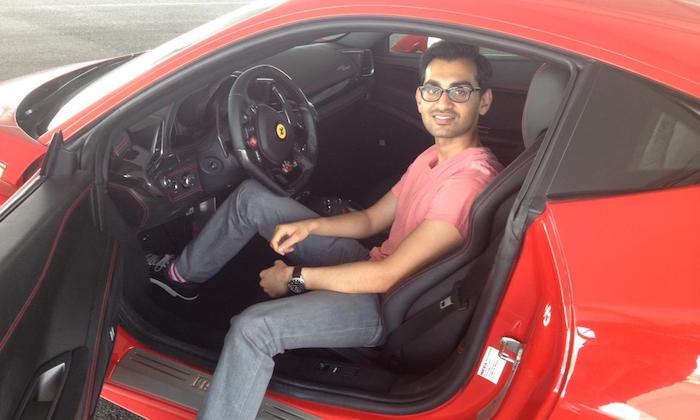
What’s one thing that you are constantly seeing on the web? Especially if you are on Instagram, Facebook, and YouTube?
Come on, take a guess…
No, I am not talking about people taking half-naked selfies of themselves or posting their lunches. I’m talking about people showing off. From taking pictures of their cars or money and even their homes to standing in front of private jets and yachts.
You know… one of those images like the one above. And if you are wondering, that isn’t my car. A friend took that picture of me when I was at the race track… heck I don’t even drive anymore (or have any more hair!).
But do you want to know a little secret?
The loudest one in the room is the weakest one in the room
Now, I didn’t come up with that quote. It’s from the movie American Gangster that stars Denzel Washington.
But sadly, that doesn’t stop people from taking advice from all of the “loud” marketers our there showing off.
But I’ll let you on in a little secret…
People who really have money don’t need to run ads showing off how much cash they have and they surely don’t care what others think about them.
I learned this from my parents, as well as a few other valuable things.
So what did my parents teach me?
I didn’t grow up with money, and I didn’t have rich parents. My first job was picking up trash, cleaning restrooms, and sweeping up vomit at a theme park.
And I don’t want anyone to feel sorry for me either. My life wasn’t bad at all. I didn’t grow up poor either.
My parents worked really hard as immigrants and eventually, they were able to provide a middle-class lifestyle for me and my sister.
But as I was growing up, my parents taught me that showing off only draws more attention and causes problems.
That’s why I don’t have “lifestyle” photos of myself. Heck, I don’t really even talk much about my personal life as I prefer to keep things private… as much as possible at least. That’s the main reason I don’t use Instagram.
See, when I was growing up, I was thankful for whatever I had.
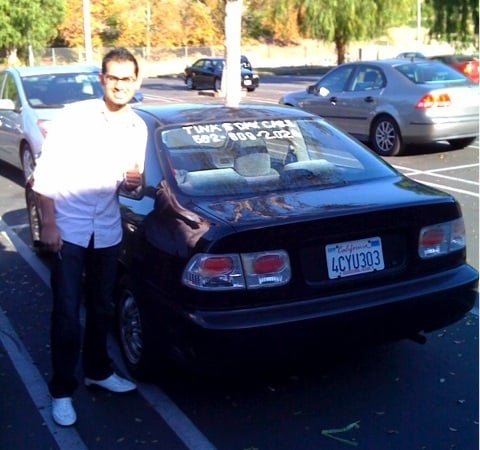
When I was growing up, that’s the car my parents gave me to drive. Luckily for me, my parents were generous enough not to make me pay for the car or even the gas.
Sure, the car had a sticker in the back window promoting my mom’s daycare business at the time, but I didn’t mind. When I would go to business meetings people would make fun of me but that didn’t bother me either.
Want to know why? I had a free car.
source https://neilpatel.com/blog/loud-is-weak/
Facebook’s collections are becoming shareable, just in time for the holidays
This holiday season, Facebook is hoping you’ll use a relatively little-known feature to share your gift ideas.
With collections, users can already save Facebook content — whether it’s a post, an ad, a video in Facebook Watch or a listing on the Marketplace. Now the company says that you’ll be able to share these collections with your Facebook friends.
The idea is to turn collections into more of a collaborative tool. To do so, you’ll need to open up a collection and then click the “invite” button. Then you can invite other users to become contributors to that collection.
A Facebook blog post explains how this collaboration might work:
If you and a group of friends are planning a holiday party, one of them can create a collection called “holiday recipes” and share with each person helping to plan. Those invited can add holiday recipes they’ve discovered on Facebook and save in the shared collection. The possibilities extend beyond the holiday season and can be useful for coordinating with friends on things like summer vacation planning, wedding registry ideas, furnishing a new apartment and more.
If you had no idea that this feature existed before now, I’m right there with you. Apparently Facebook has been testing “save” capabilities since 2014, which (quietly) evolved into the collections feature last year.
The company says “millions” of people are already using collections. Now that they’re becoming more of a social tool, it seems that Facebook is ready to do more to promote them.
source https://techcrunch.com/2018/12/04/facebook-collections-3/
Monday, 3 December 2018
Tumblr will delete all porn from its platform
Tumblr, a microblogging service that’s impact on internet culture has been massive and unique, is preparing for a massive change that’s sure to upset many of its millions of users.
On December 17, Tumblr will be banning porn, errr “adult content,” from its site and encouraging users to flag that content for removal. Existing adult content will be set to a “private mode” viewable only to the original poster.
What does “adult content” even mean? Well, according to Tumblr, the ban means the removal of any media that depicts “real-life human genitals or female-presenting nipples, and any content—including photos, videos, GIFs and illustrations—that depicts sex acts.”
This is a lot more complicated than just deleting some hardcore porn from the site; over the past several years Tumblr has become a hub for communities and artists with more adult themes. This has largely been born out of the fact that adult content has been disallowed from other multimedia-focused social platforms. There are bans on nudity and sexual content on Instagram and Facebook, though Twitter has more relaxed standards.
Why now? The Tumblr app was removed from the iOS app store several weeks ago due to an issue with its content filtering that led the company to issue a statement. “We’re committed to helping build a safe online environment for all users, and we have a zero tolerance policy when it comes to media featuring child sexual exploitation and abuse,” the company had detailed. “We’re continuously assessing further steps we can take to improve and there is no higher priority for our team.”
We’ve reached out to Tumblr for further comment.
Update: In a blog post titled “A better, more positive Tumblr,” the company’s CEO Jeff D’Onofrio minimized claims that the content ban was related to recent issues surrounding child porn, and is instead intended to make the platform one “where more people feel comfortable expressing themselves.”
“As Tumblr continues to grow and evolve, and our understanding of our impact on our world becomes clearer, we have a responsibility to consider that impact across different age groups, demographics, cultures, and mindsets,” the post reads. “Bottom line: There are no shortage of sites on the internet that feature adult content. We will leave it to them and focus our efforts on creating the most welcoming environment possible for our community.”
The imminent “adult content” ban will not apply to media connected with breastfeeding, birth or more general “health-related situations” like surgery, according to the company.
Tumblr is attempting to make aims to minimize the impact on the site’s artistic community as well, but this level of nuance is going to be incredibly difficult for them to enforce uniformly and will more than likely lead to a lot of frustrated users being told that their content does not qualify as “art.”
Tumblr is also looking to minimize impact on the more artistic storytelling, “such as erotica, nudity related to political or newsworthy speech, and nudity found in art, such as sculptures and illustrations, are also stuff that can be freely posted on Tumblr.”
I don’t know how much it needs to be reiterated that child porn is a major issue plaguing the web, but a blanket ban on adult content on a platform that has gathered so many creatives working with NSFW themes is undoubtedly going to be a pretty controversial decision for the company.
source https://techcrunch.com/2018/12/03/tumblr-no-more-porn/
Tumblr will delete all porn from the platform
Tumblr, a microblogging service that’s impact on internet culture has been massive and unique, is preparing for a massive change that’s sure to upset many of its millions of users.
On December 17, Tumblr will be banning porn, errr “adult content,” from its site and encouraging users to flag that content for removal. Existing adult content will be set to a “private mode” viewable only to the original poster.
What does “adult content” even mean? Well, according to Tumblr, the ban means the removal of any media that depicts “real-life human genitals or female-presenting nipples, and any content—including photos, videos, GIFs and illustrations—that depicts sex acts.”
This is a lot more complicated than just deleting some hardcore porn from the site; over the past several years Tumblr has become a hub for communities and artists with more adult themes. This has largely been born out of the fact that adult content has been disallowed from other multimedia-focused social platforms. There are bans on nudity and sexual content on Instagram and Facebook, though Twitter has more relaxed standards.
Why now? The Tumblr app was removed from the iOS app store several weeks ago due to an issue with its content filtering that led the company to issue a statement. “We’re committed to helping build a safe online environment for all users, and we have a zero tolerance policy when it comes to media featuring child sexual exploitation and abuse,” the company had detailed. “We’re continuously assessing further steps we can take to improve and there is no higher priority for our team.”
We’ve reached out to Tumblr for further comment.
Update: In a blog post titled “A better, more positive Tumblr,” the company’s CEO Jeff D’Onofrio minimized claims that the content ban was related to recent issues surrounding child porn, and is instead intended to make the platform one “where more people feel comfortable expressing themselves.”
“As Tumblr continues to grow and evolve, and our understanding of our impact on our world becomes clearer, we have a responsibility to consider that impact across different age groups, demographics, cultures, and mindsets,” the post reads. “Bottom line: There are no shortage of sites on the internet that feature adult content. We will leave it to them and focus our efforts on creating the most welcoming environment possible for our community.”
The imminent “adult content” ban will not apply to media connected with breastfeeding, birth or more general “health-related situations” like surgery, according to the company.
Tumblr is attempting to make aims to minimize the impact on the site’s artistic community as well, but this level of nuance is going to be incredibly difficult for them to enforce uniformly and will more than likely lead to a lot of frustrated users being told that their content does not qualify as “art.”
Tumblr is also looking to minimize impact on the more artistic storytelling, “such as erotica, nudity related to political or newsworthy speech, and nudity found in art, such as sculptures and illustrations, are also stuff that can be freely posted on Tumblr.”
I don’t know how much it needs to be reiterated that child porn is a major issue plaguing the web, but a blanket ban on adult content on a platform that has gathered so many creatives working with NSFW themes is undoubtedly going to be a pretty controversial decision for the company.
source https://techcrunch.com/2018/12/03/tumblr-no-more-porn/
7 Search Ranking Factors Analyzed: A Follow-Up Study
Posted by Jeff_Baker
Grab yourself a cup of coffee (or two) and buckle up, because we’re doing maths today.
Again.
Back it on up...
A quick refresher from last time: I pulled data from 50 keyword-targeted articles written on Brafton’s blog between January and June of 2018.
We used a technique of writing these articles published earlier on Moz that generates some seriously awesome results (we’re talking more than doubling our organic traffic in the last six months, but we will get to that in another publication).
We pulled this data again… Only I updated and reran all the data manually, doubling the dataset. No APIs. My brain is Swiss cheese.
We wanted to see how newly written, original content performs over time, and which factors may have impacted that performance.
Why do this the hard way, dude?
“Why not just pull hundreds (or thousands!) of data points from search results to broaden your dataset?”, you might be thinking. It’s been done successfully quite a few times!
Trust me, I was thinking the same thing while weeping tears into my keyboard.
The answer was simple: I wanted to do something different from the massive aggregate studies. I wanted a level of control over as many potentially influential variables as possible.
By using our own data, the study benefited from:
- The same root Domain Authority across all content.
- Similar individual URL link profiles (some laughs on that later).
- Known original publish dates and without reoptimization efforts or tinkering.
- Known original keyword targets for each blog (rather than guessing).
- Known and consistent content depth/quality scores (MarketMuse).
- Similar content writing techniques for targeting specific keywords for each blog.
You will never eliminate the possibility of misinterpreting correlation as causation. But controlling some of the variables can help.
As Rand once said in a Whiteboard Friday, “Correlation does not imply causation (but it sure is a hint).”
Caveat:
What we gained in control, we lost in sample size. A sample size of 96 is much less useful than ten thousand, or a hundred thousand. So look at the data carefully and use discretion when considering the ranking factors you find most likely to be true.
This resource can help gauge the confidence you should put into each Pearson Correlation value. Generally, the stronger the relationship, the smaller sample size needed to be be confident in the results.
So what exactly have you done here?
We have generated hints at what may influence the organic performance of newly created content. No more, and no less. But they are indeed interesting hints and maybe worth further discussion or research.
What have you not done?
We have not published sweeping generalizations about Google’s algorithm. This post should not be read as a definitive guide to Google’s algorithm, nor should you assume that your site will demonstrate the same correlations.
So what should I do with this data?
The best way to read this article, is to observe the potential correlations we observed with our data and consider the possibility of how those correlations may or may not apply to your content and strategy.
I’m hoping that this study takes a new approach to studying individual URLs and stimulates constructive debate and conversation.
Your constructive criticism is welcome, and hopefully pushes these conversations forward!
The stat sheet
So quit jabbering and show me the goods, you say? Alright, let’s start with our stats sheet, formatted like a baseball card, because why not?:

*Note: Only blogs with complete ranking data were used in the study. We threw out blogs with missing data rather than adding arbitrary numbers.
And as always, here is the original data set if you care to reproduce my results.
So now the part you have been waiting for...
The analysis
To start, please use a refresher on the Pearson Correlation Coefficient from my last blog post, or Rand’s.
1. Time and performance
I started with a question: “Do blogs age like a Macallan 18 served up neat on a warm summer Friday afternoon, or like tepid milk on a hot summer Tuesday?”
Does the time indexed play a role in how a piece of content performs?
Correlation 1: Time and target keyword position
First we will map the target keyword ranking positions against the number of days its corresponding blog has been indexed. Visually, if there is any correlation we will see some sort of negative or positive linear relationship.

There is a clear negative relationship between the two variables, which means the two variables may be related. But we need to go beyond visuals and use the PCC.
|
Days live vs. target keyword position |
|
|---|---|
|
PCC |
-.343 |
|
Relationship |
Moderate |

The data shows a moderate relationship between how long a blog has been indexed and the positional ranking of the target keyword.
But before getting carried away, we shouldn’t solely trust one statistical method and call it a day. Let’s take a look at things another way: Let’s compare the average age of articles whose target keywords rank in the top ten against the average age of articles whose target keywords rank outside the top ten.
|
Average age of articles based on position |
|
|---|---|
|
Target KW position ≤ 10 |
144.8 days |
|
Target KW position > 10 |
84.1 days |
Now a story is starting to become clear: Our newly written content takes a significant amount of time to fully mature.
But for the sake of exhausting this hint, let’s look at the data one final way. We will group the data into buckets of target keyword positions, and days indexed, then apply them to a heatmap.
This should show us a clear visual clustering of how articles perform over time.

This chart, quite literally, paints a picture. According to the data, we shouldn’t expect a new article to realize its full potential until at least 100 days, and likely longer. As a blog post ages, it appears to gain more favorable target keyword positioning.
Correlation 2: Time and total ranking keywords on URL
You’ll find that when you write an article it will (hopefully) rank for the keyword you target. But often times it will also rank for other keywords. Some of these are variants of the target keyword, some are tangentially related, and some are purely random noise.
Instinct will tell you that you want your articles to rank for as many keywords as possible (ideally variants and tangentially related keywords).
Predictably, we have found that the relationship between the number of keywords an article ranks for and its estimated monthly organic traffic (per SEMrush) is strong (.447).
We want all of our articles to do things like this:

We want lots of variants each with significant search volume. But, does an article increase the total number of keywords it ranks for over time? Let’s take a look.

Visually this graph looks a little murky due to the existence of two clear outliers on the far right. We will first run the analysis with the outliers, and again without. With the outliers, we observe the following:
|
Days live vs. total keywords ranking on URL (w/outliers) |
|
|---|---|
|
PCC |
.281 |
|
Relationship |
Weak/borderline moderate |

There appears to be a relationship between the two variables, but it isn’t as strong. Let’s see what happens when we remove those two outliers:

Visually, the relationship looks stronger. Let’s look at the PCC:
|
Days live vs. total keywords ranking on URL (without outliers) |
|
|---|---|
|
PCC |
.390 |
|
Relationship |
Moderate/borderline strong |

The relationship appears to be much stronger with the two outliers removed.
But again, let’s look at things another way.
Let’s look at the average age of the top 25% of articles and compare them to the average age of the bottom 25% of articles:
|
Average age of top 25% of articles versus bottom 25% |
|
|---|---|
|
Top 25% |
148.9 days |
|
Bottom 25% |
73.8 days |
This is exactly why we look at data multiple ways! The top 25% of blog posts with the most ranking keywords have been indexed an average of 149 days, while the bottom 25% have been indexed 74 days — roughly half.
To be fully sure, let’s again cluster the data into a heatmap to observe where performance falls on the time continuum:

We see a very similar pattern as in our previous analysis: a clustering of top-performing blogs starting at around 100 days.
Time and performance assumptions
You still with me? Good, because we are saying something BIG here. In our observation, it takes between 3 and 5 months for new content to perform in organic search. Or at the very least, mature.
To look at this one final way, I’ve created a scatterplot of only the top 25% of highest performing blogs and compared them to their time indexed:

There are 48 data plots on this chart, the blue plots represent the top 25% of articles in terms of strongest target keyword ranking position. The orange plots represent the top 25% of articles with the highest number of keyword rankings on their URL. (These can be, and some are, the same URL.)
Looking at the data a little more closely, we see the following:

90% of the top 25% of highest-performing content took at least 100 days to mature, and only two articles took less than 75 days.
Time and performance conclusion
For those of you just starting a content marketing program, remember that you may not see the full organic potential for your first piece of content until month 3 at the earliest. And, it takes at least a couple months of content production to make a true impact, so you really should wait a minimum of 6 months to look for any sort of results.
In conclusion, we expect new content to take at least 100 days to fully mature.
2. Links
But wait, some of you may be saying. What about links, buddy? Articles build links over time, too!
It stands to reason that, over time, a blog will gain links (and ranking potential) over time. Links matter, and higher positioned rankings gain links at a faster rate. Thus, we are at risk of misinterpreting correlation for causation if we don’t look at this carefully.
But what none of you know, that I know, is that being the terrible SEO that I am, I had no linking strategy with this campaign.
And I mean zero strategy. The average article generated 1.3 links from .5 linking domains.
Nice.
|
Linking domains vs. target keyword position |
|
|---|---|
|
PCC |
-.022 |
|
Relationship |
None |
|
Average linking domains to top 25% of articles |
.46 |
|
Average linking domains to bottom 25% of articles |
.46 |
The one thing consistent across all the articles was a shocking and embarrassing lack of inbound links. This is demonstrated by an insignificant correlation coefficient of -.022. The same goes for the total number of links per URL, with a correlation coefficient of -.029.
These articles appear to have performed primarily on their content rather than inbound links.
(And they certainly would have performed much better with a strong, or any, linking strategy. Nobody is arguing the value of links here.) But mostly...
Shame on me.
Shame. Shame. Shame.
But on a positive note, we were able to generate a more controlled experiment on the effects of time and blog performance. So, don’t fire me just yet?
Note: It would be interesting to pull link quality metrics into the discussion (for the precious few links we did earn) rather than total volume. However, after a cursory look at the data, nothing stood out as being significant.
3. Word count
Content marketers and SEOs love talking about word count. And for good reason. When we collectively agreed that “quality content” was the key to rankings, it would stand to reason that longer content would be more comprehensive, and thus do a better job of satisfying searcher intent. So let’s test that theory.
Correlation 1: Target keyword position versus total word count
Will longer articles increase the likelihood of ranking for the keyword you are targeting?

Not in our case. To be sure, let’s run a similar analysis as before.
|
Word count vs. target keyword position |
|
|---|---|
|
PCC |
.111 |
|
Relationship |
Negligible |
|
Average word count of top 25% articles |
1,774 |
|
Average word count of bottom 25% articles |
1,919 |

The data shows no impact on rankings based on the length of our articles.
Correlation 2: Total keywords ranking on URL versus word count
One would think that longer content would result in is additional ranking keywords, right? Even by accident, you would think that the more related topics you discuss in an article, the more keywords you will rank for. Let’s see if that’s true:
|
Total keywords ranking on URL vs. word count |
|
|---|---|
|
PCC |
-.074 |
|
Relationship |
None |

Not in this case.
Word count, speculative tangent
So how can it be that so many studies demonstrate higher word counts result in more favorable rankings? Some reconciliation is in order, so allow me to speculate on what I think may be happening in these studies.
- Most likely: Measurement techniques. These studies generally look at one factor relative to rankings: average absolute word count based on position. (And, there actually isn’t much of a difference in average word count between position one and ten.)
 As we are demonstrating in this article, there may be many other factors at play that need to be isolated and tested for correlations in order to get the full picture, such as: time indexed, on-page SEO (to be discussed later), Domain Authority, link profile, and depth/quality of content (also to be discussed later with MarketMuse as a measure). It’s possible that correlation does not imply correlation, and by using word count averages as the single method of measure, we may be painting too broad of a stroke.
- Likely: High quality content is longer, by nature. We know that “quality content” is discussed in terms of how well a piece satisfies the intent of the reader. In an ideal scenario, you will create content that fully satisfies everything a searcher would want to know about a given topic. Ideally you own the resource center for the topic, and the searcher does not need to revisit SERPs and weave together answers from multiple sources. By nature, this type of comprehensive content is quite lengthy. Long-form content is arguably a byproduct of creating for quality. Cyrus Shepard does a better job of explaining this likelihood here.
- Less likely: Long-form threshold. The articles we wrote for this study ranged from just under 1,000 words to nearly as high as 4,000 words. One could consider all of these as “long-form content,” and perhaps Google does as well. Perhaps there is a word count threshold that Google uses.
This is all speculation. What we can say for certain is that all our content is 900 words and up, and shows no incremental benefit to be had from additional length.
Feel free to disagree with any (or all) of my speculations on my interpretation of the discrepancies of results, but I tend to have the same opinion as Brian Dean with the information available.
4. MarketMuse
At this point, most of you are familiar with MarketMuse. They have created a number of AI-powered tools that help with content planning and optimization.
We use the Content Optimizer tool, which evaluates the top 20 results for any keyword and generates an outline of all the major topics being discussed in SERPs. This helps you create content that is more comprehensive than your competitors, which can
source https://moz.com/blog/7-search-ranking-factors-analyzed-follow-up-study
Saturday, 1 December 2018
Now you can read the controversial Definers research about George Soros and Facebook
Facebook is still dealing with the fallout from a New York Times report outlining the company’s strategy to fight back against criticism, particularly its work with Definers Public Affairs, an opposition research firm with ties to the Republican Party.
That work included a document that Definers sent to reporters suggesting ties between George Soros and progressive political groups criticizing Facebook. The Times story described the broad strokes of the claims made by Definers, but the document itself has not been shared with the public — until today, when it was published by BuzzFeed.
At this point, the contents aren’t particularly revelatory, but the document is still worth reading, since it’s at the center of the recent controversy.
It’s titled “Freedom From Facebook Potential Funding,” and it begins:
Recently, a number of progressive groups came together to form the Freedom From Facebook campaign which has a six-figure ad budget. It is not clear who is providing the large amount of funding for the campaign but at least four of the groups in the coalition receive funding or are aligned with George Soros who has publicly criticized Facebook. It is very possible that Soros is funding Freedom From Facebook.
The document goes on to point out connections between Soros and several of the groups involved in Freedom From Facebook, and it notes Soros’ public criticism of Facebook and Google. On its own, the document seems “largely innocuous” (as BuzzFeed put it), but it’s become controversial for potentially playing into anti-Semitic conspiracy theories about Soros.
A Freedom From Facebook spokesperson has said that no money from Soros was used to fund the campaign — in fact, Axios reported that its initial funding came from David Magerman, a Pennsylvania-based philanthropist and former hedge fund executive.
According to BuzzFeed, this is one of at least two documents that Definers prepared after Soros made critical remarks about Facebook and Google at Davos.
Meanwhile, CEO Mark Zuckerberg and COO Sheryl Sandberg have denied knowledge of Definers’ work for Facebook, and outgoing head of public policy Elliot Schrage took responsibility for hiring the firm. But Facebook later acknowledged that Sandberg had asked the communications team to research Soros’ financial ties after he criticized the company, and reporting by my colleague Taylor Hatmaker suggests that Sandberg was more aware of Definers’ work than initially acknowledged.
When reached for comment, a Facebook spokesperson pointed us to Schrage’s post and said the company has nothing further to add.
source https://techcrunch.com/2018/12/01/facebook-definers-george-soros/